Hi Erik, Roland, all,
After our discussion on last week's telecon, I followed Roland's instructions on how to get the branch which has changes to how Carpet handles prolongation with respect to OpenMP. I reran my simple scaling test on Stampede Skylake nodes using this branch of Carpet (rhaas/openmp-tasks) to test the scalability.
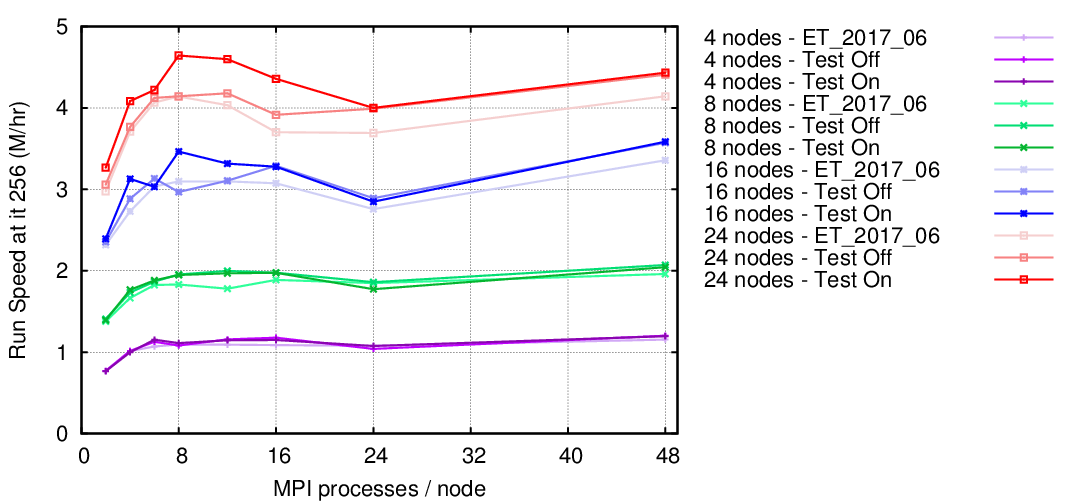
Attached is a plot showing the speeds for a variety of number of nodes and how the 48 threads are distributed on the nodes between MPI processes and OpenMP threads. I did this for three versions of the ETK. 1. Fresh checkout of ET_2017_06. 2. The ET_2017_06 with Carpet switched to the rhaas/openmp-tasks (labelled "Test On") 3. Again with the checkout from #2, but without the parameters to enable the new prolongation code (labelled "Test Off"). The run speeds used were grabbed at iteration 256 from Carpet::physical_time_per_hour. No IO or regridding.
For 4 and 8 nodes (ie 192 and 384 cores), there wasn't much difference between the 3 trials. However, for 16 and 24 nodes (768 and 1152 cores), we see some improvement in run speed (10-15%) for many choices of distribution of threads, again with a slight preference for 8 ranks/node.
I also ran the previous test (not using the openmp-tasks branch) on comet, and found similar results as before.
Thanks, Jim
On 01/21/2018 01:07 PM, Erik Schnetter wrote:
James
I looked at OpenMP performance in the Einstein Toolkit a few months ago, and I found that Carpet's prolongation operators are not well parallelized. There is a branch in Carpet (and a few related thorns) that apply a different OpenMP parallelization strategy, which seems to be more efficient. We are currently looking into cherry-picking the relevant changes from this branch (there are also many unrelated changes, since I experimented a lot) and putting them back into the master branch.
These changes only help with prolongation, which seems to be a major contributor to non-OpenMP-scalability. I experimented with other changes as well. My findings (unfortunately without good solutions so far) are:
- The standard OpenMP parallelization of loops over grid functions is
not good for data cache locality. I experimented with padding arrays, ensuring that loop boundaries align with cache line boundaries, etc., but this never worked quite satisfactorily -- MPI parallelization is still faster than OpenMP. In effect, the only reason one would use OpenMP is once one encounters MPI's scalability limits, so that OpenMP's non-scalability is less worse.
- We could overlap calculations with communication. To do so, I have
experimental changes that break loops over grid functions into tiles. Outer tiles need to wait for communication (synchronization or parallelization) to finish, while inner tiles can be calculated right away. Unfortunately, OpenMP does not support open-ended threads like this, so I'm using Qthreads https://github.com/Qthreads/qthreads and FunHPC https://bitbucket.org/eschnett/funhpc.cxx for this. The respective changes to Carpet, the scheduler, and thorns are significant, and I couldn't prove any performance improvements yet. However, once we removed other, more prominent non-scalability causes, I hope that this will become interesting.
I haven't been attending the ET phone calls recently because Monday mornings aren't good for me schedule-wise. If you are interested, then we can ensure that we both attend at the same time and then discuss this. We need to make sure the Roland Haas is then also attending.
-erik
On Sat, Jan 20, 2018 at 10:21 AM, James Healy <jchsma@rit.edu mailto:jchsma@rit.edu> wrote:
Hello all,

I am trying to run on the new skylake processors on Stampede2 and
while the run speeds we are obtaining are very good, we are
concerned that we aren't optimizing properly when it comes to
OpenMP.  For instance, we see the best speeds when we use 8 MPI
processors per node (with 6 threads each for a total of 48 total
threads/node).  Based on the architecture, we were expecting to
see the best speeds with 2 MPI/node.  Here is what I have tried:

 1. Using the simfactory files for stampede2-skx (config file, run
    and submit scripts, and modules loaded) I compiled a version
    of ET_2017_06 using LazEv (RIT's evolution thorn) and
    McLachlan and submitted a series of runs that change both the
    number of nodes used, and how I distribute the 48 threads/node
    between MPI processes.
 2. I use a standard low resolution grid, with no IO or
    regridding.  Parameter file attached.
 3. Run speeds are measured from Carpet::physical_time_per_hour at
    iteration 256.
 4. I tried both with and without hwloc/SystemTopology.
 5. For both McLachlan and LazEv, I see similar results, with 2
    MPI/node giving the worst results (see attached plot for
    McLachlan) and a slight preferences for 8 MPI/node.

So my questions are:

 1. Has there been any tests run by any other users on stampede2 skx?
 2. Should we expect 2 MPI/node to be the optimal choice?
 3. If so, are there any other configurations we can try that
    could help optimize?

Thanks in advance!

Jim Healy


_______________________________________________
Users mailing list
Users@einsteintoolkit.org <mailto:Users@einsteintoolkit.org>
http://lists.einsteintoolkit.org/mailman/listinfo/users
<http://lists.einsteintoolkit.org/mailman/listinfo/users>
-- Erik Schnetter <schnetter@cct.lsu.edu mailto:schnetter@cct.lsu.edu> http://www.perimeterinstitute.ca/personal/eschnetter/